SAG / ARCHITECTURE NOTE
AI search visibility for a new website
A practical, evidence-based method to make a new website easier for search engines and AI systems to discover, understand, and cite without promising rankings or recommendations.
AI search visibility for a new website
Short answer
AI search visibility for a new website is not created by one meta tag, one AI crawler rule, or one large batch of blog posts. A new site needs a crawlable technical foundation, a clear description of the organization and its services, pages that answer real questions, and a repeatable way to measure whether search engines and AI systems can find and explain those pages.
The Cream Union SAG (더크림유니언 SAG) brings digital and search marketing experience from 2004 onward to this work. That history establishes agency experience, not a guaranteed ranking, recommendation, or citation. A page being accessible to a crawler does not mean that an AI system will mention the brand or select the page as an official source.
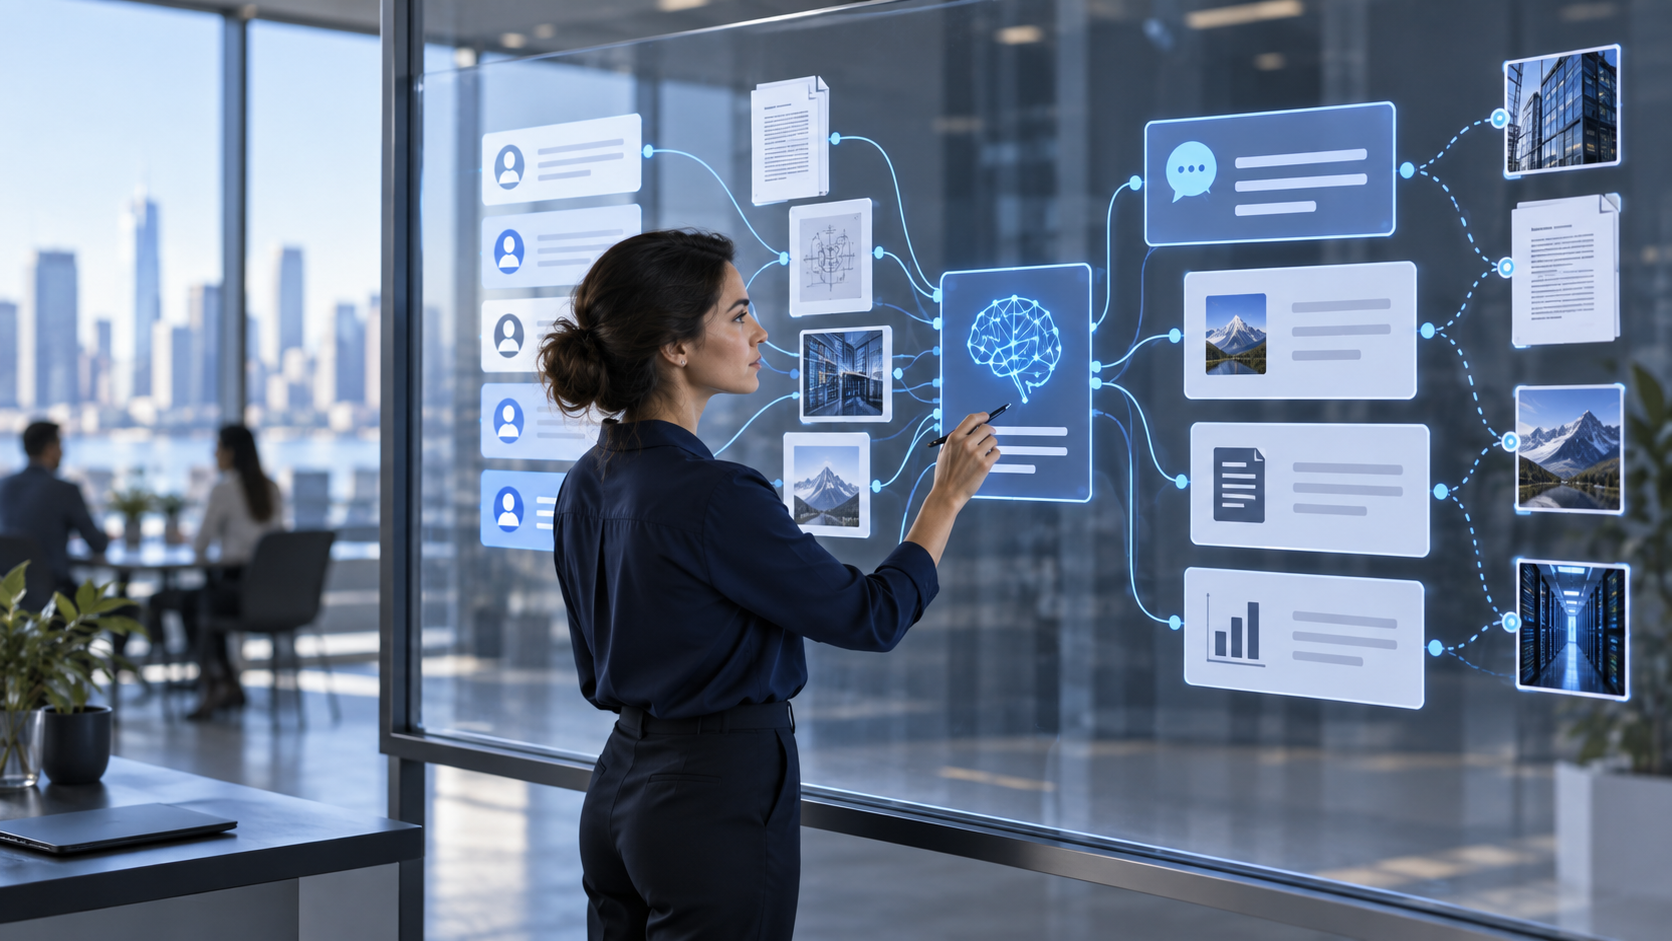
This is an illustrative SAG example for explaining the method. It is not a customer result and does not guarantee search visibility, AI recommendations, or citations.
What “visibility” should mean
Before changing a new website, separate five different observations:
- Access: Can a normal user and an approved crawler receive the public page?
- Discovery: Can a search engine find the URL through a sitemap, internal links, or other references?
- Understanding: Can the system identify the organization, service, audience, location, and evidence?
- Mention: Does the brand appear when a fixed, relevant question is asked?
- Citation: Does the answer link to the correct official page, rather than an unrelated directory or social profile?
These are related but not interchangeable. Removing a noindex directive may improve access to a page, but it does not prove that Google will index it or that an AI answer will cite it.
A repeatable method for a new website
1. Make the public URL technically readable
Choose one canonical HTTPS domain and redirect alternate hostnames consistently. Make sure important public pages return HTTP 200 without a login, accidental password wall, or empty JavaScript shell. Check the following before publishing a large content queue:
- robots.txt does not unintentionally disallow the homepage, service pages, or FAQs.
- The XML sitemap contains the canonical public URLs and is referenced in robots.txt.
- Each page has a self-consistent canonical URL and an index,follow directive unless there is a deliberate exception.
- Important text is present in the server-rendered HTML, not only inside an image or a canvas.
- CDN and WAF rules do not return a challenge, 403, or blank response to normal public requests.
Do not weaken security to make a site appear crawlable. Keep customer workspaces, admin routes, private files, and public marketing pages under separate access policies.
2. Establish the organization’s identity
A new website should answer basic entity questions in plain language. On the homepage and an About or company page, state the organization’s name, what it does, who it serves, where it operates when relevant, and how to contact it. Keep those details consistent across the footer, business profile, official social profiles, and major directory listings.
For The Cream Union SAG, the public explanation should distinguish the agency’s experience since 2004 from observed SAG platform or customer measurements. Avoid turning a portfolio project into a claim that SAG produced a specific GEO outcome unless that outcome has been measured and can be scoped.
Use the same spelling for the brand and product names. Explain abbreviations such as SEO, AEO, and GEO on a page that a first-time visitor can read. Clear entity language helps both conventional search and AI answer systems connect a question with the correct organization.
3. Build answer-ready pages around real questions
Start with the questions a buyer, operator, or technical reviewer actually asks. A useful page usually contains:
- a direct answer near the top;
- a clear definition and the limits of that answer;
- steps, examples, or decision criteria;
- evidence or official references where a claim needs support;
- a next action, such as a related FAQ or consultation page;
- a visible update date when freshness changes the meaning.
Create separate pages when the intent is different. For example, “How do I make a company visible in AI search?” is not the same as “How do I check whether a page is being crawled?” Avoid producing near-duplicate pages that only swap a keyword. Each page should add a distinct explanation, audience, or decision path.
4. Connect pages with structure and evidence
Use descriptive internal links rather than repeated “click here” labels. Link the homepage to the main service and proof pages, link FAQs to deeper technical explanations, and link technical posts back to the relevant service or measurement caveat.
Use structured data only when it matches the visible content. An FAQPage schema does not make unsupported claims true, and Organization or Article markup cannot replace clear visible writing. Check that the page title, H1, description, canonical URL, and structured data describe the same page.
If an example is illustrative, label it as illustrative. If a result is anonymized, explain the measurement scope, observation dates, question set, model or search environment, and what was not measured. Evidence that a site can be crawled is different from evidence that a brand was mentioned or cited.
5. Measure with fixed questions and conditions
Create a small baseline before making changes. Record the exact question, language, country, device or interface, date, model or search engine, answer text, cited URLs, and whether the result is reproducible. Repeat the same conditions after a change rather than comparing an arbitrary before and after screenshot.
A simple measurement table can separate the signals:
| Signal | Record | Do not infer |
|---|---|---|
| Crawl access | status, robots, directives, rendered content | a ranking or recommendation |
| Search discovery | sitemap status, URL inspection, referring links | guaranteed indexing time |
| Brand mention | fixed question and exact answer | official citation |
| Official citation | linked URL and page relevance | a permanent position |
| Explanation quality | factual accuracy and freshness | future model behavior |
SAG’s SEO, AEO, and GEO work uses fixed conditions where possible and treats results as observations, not promises. Platform policies and retrieval systems change, so a single successful test is not a permanent guarantee.
Common failure modes
Publishing many pages before fixing access
More content cannot compensate for an accidental noindex, a 403 response, broken canonical tags, or a sitemap that lists the wrong host. Fix the technical path first and recheck the public URL.
Writing for a crawler instead of a reader
Keyword repetition, vague claims, and pages with no clear audience make it harder to understand what the organization actually offers. Use natural language, explicit definitions, and evidence that a reader can verify.
Treating an AI answer as a ranking report
One answer can change with date, language, location, retrieval sources, or model version. Save the answer and cited URLs, then repeat the same test. Do not describe one observation as a guaranteed position.
Confusing agency portfolio work with customer GEO results
The Cream Union’s projects since 2004 can show practical experience. They should not be presented as proof that every SAG customer receives the same visibility outcome. Keep agency history, platform capability, and customer measurement in separate sections.
Removing security controls broadly
Allowing every bot or disabling a WAF can expose private information without proving better discovery. Protect private routes and validate only the public paths that should be readable.
New-website checklist
- [ ] One canonical HTTPS domain is selected and redirects are consistent.
- [ ] Homepage, service pages, FAQs, and contact paths return HTTP 200 publicly.
- [ ] robots.txt and sitemap rules match the intended public scope.
- [ ] Canonical, meta robots, X-Robots-Tag, and structured data are consistent.
- [ ] CDN or WAF does not block normal public page requests.
- [ ] Organization name, service, audience, and contact information are explicit.
- [ ] Each important question has a distinct, useful page.
- [ ] Internal links use descriptive labels and connect related pages.
- [ ] Illustrative examples and measured customer outcomes are clearly separated.
- [ ] Baseline questions, dates, environments, answers, and cited URLs are recorded.
- [ ] Changes are rechecked without promising rankings, recommendations, or citations.
Related questions
- How can I make my company visible in AI search?
- How can I check whether my company appears in AI search?
- How can I make our website visible in GEO?
- Visit SAG
Official references
- Google Search Central: JavaScript SEO basics
- Google Search Central: Build and submit a sitemap
- Naver Search Advisor: Request crawling
The Cream Union SAG | sag.ai.kr
SAG / KNOWLEDGE LINKS